Ji Soo Lee
⚪️ Ph.D. Student, KAIST
⚪️ jislee [AT] kaist.ac.kr
About Me
I am a Ph.D. student in the MLV (Machine Learning & Vision) Lab at KAIST, South Korea, advised by Prof. Hyunwoo J. Kim. I received my M.S. from the same lab and my B.S. in Computer Science and Engineering from Korea University. My research interests lie in multi-modal understanding and reasoning, with an emphasis on post-training (preference optimization and reasoning distillation) and on agentic AI (skill and harness optimization). Previously, I interned at Meta Reality Labs, where I worked on multimodal reasoning over real-world wearable data.
News
- [2026 Sept] Our paper RASO, a collaboration with Meta, is now available on arXiv.
- [2026 Sept] Our paper VideoEcho-r1, a collaboration with Google Cloud, has been accepted to NeurIPS 2026.
- [2026 Sept] Our paper WearableQA, a collaboration with Meta, is now available on arXiv.
- [2026 July] Our paper SVMemAgent has been accepted to the Wearable AI Workshop @ ECCV 2026.
- [2025 Aug] Our paper CaRe-DPO has been accepted to EMNLP 2025 as findings.
- [2025 Jun] Our paper BLiM, a collaboration with Meta, has been accepted to ICCV 2025 as Highlight.
- [2025 Jan] Our paper VidChain has been accepted to AAAI 2025.
- [2023 Oct] Our paper Flipped-VQA has been accepted to EMNLP 2023.
- [2023 Jul] Our paper OVQA has been accepted to ICCV 2023.
 Google Cloud, has been accepted to NeurIPS 2026.
Publications
Most recent publications on Google Scholar.
* indicates equal contribution.
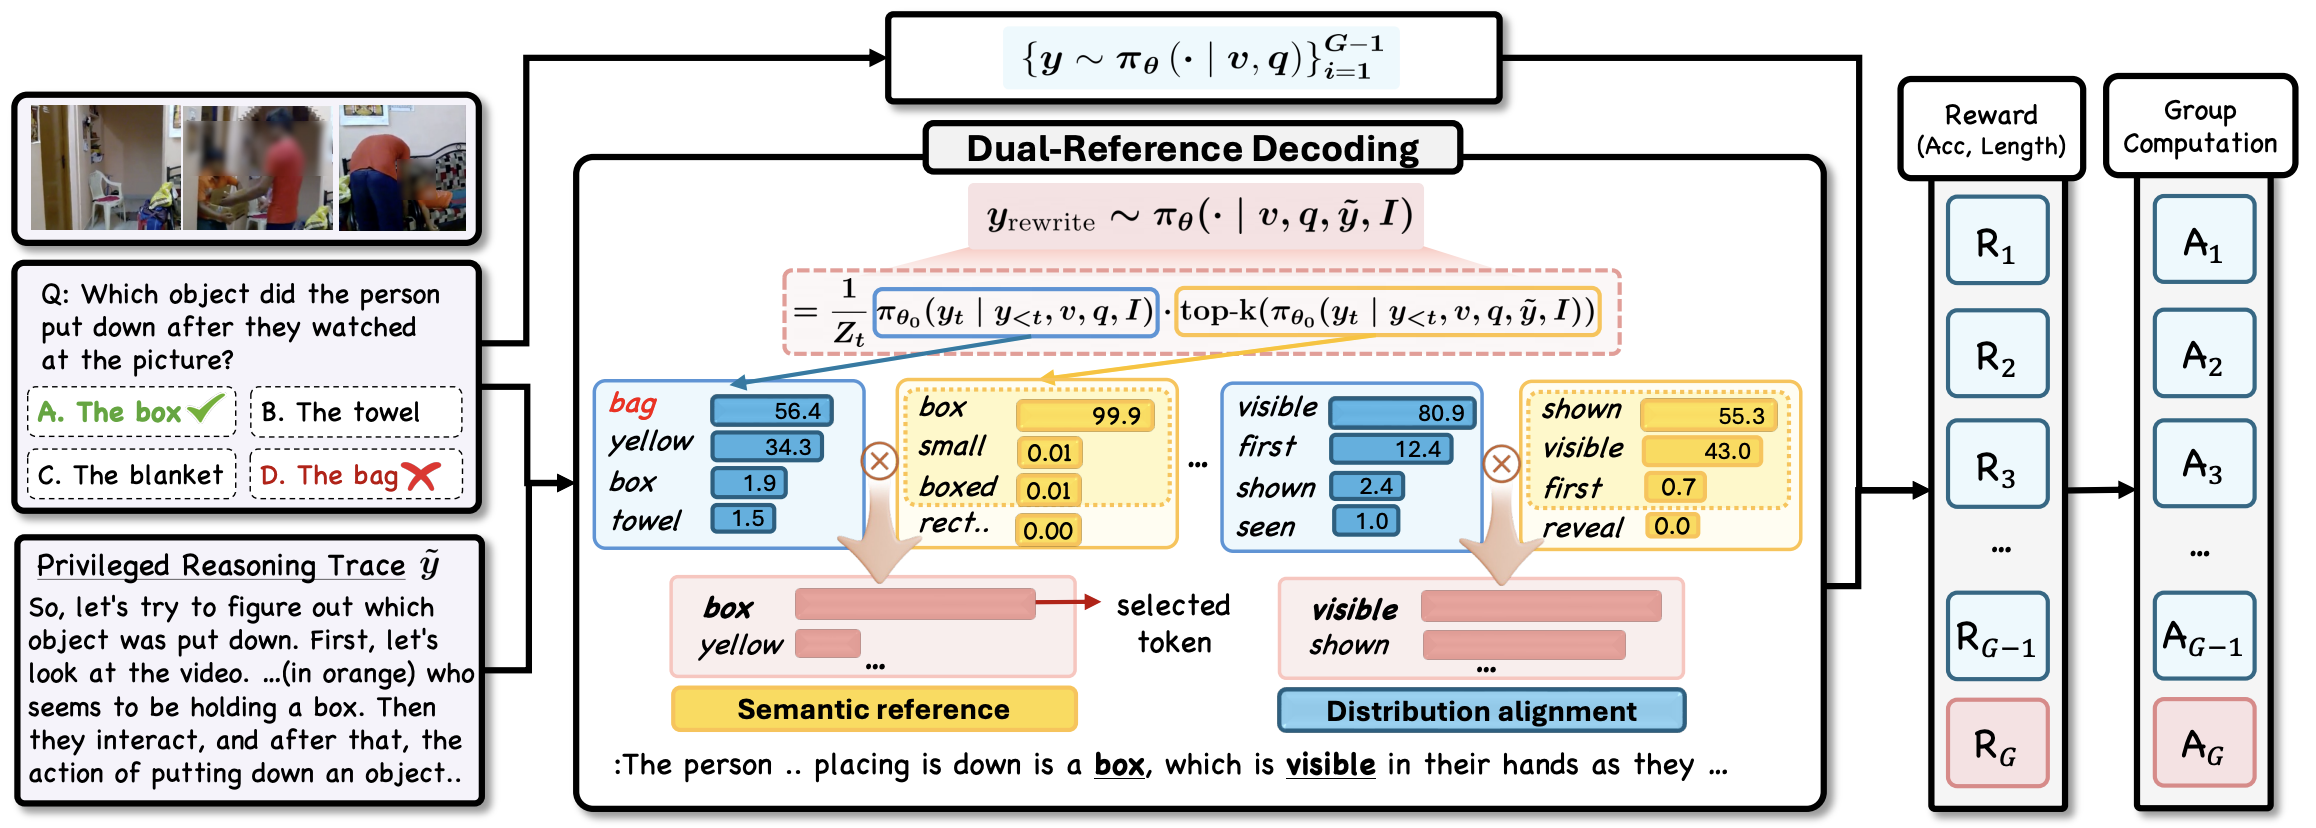
Reason in the Words You Speak: Idiolectal Paraphrasing Off-Policy Traces for Reasoning Distillation in VideoLLMs
Ji Soo Lee, Jinyoung Park, Seohyun Lee, Jongha Kim, Joonmyung Choi, Jinsung Yoon, Hyunwoo J. Kim
NeurIPS 2026
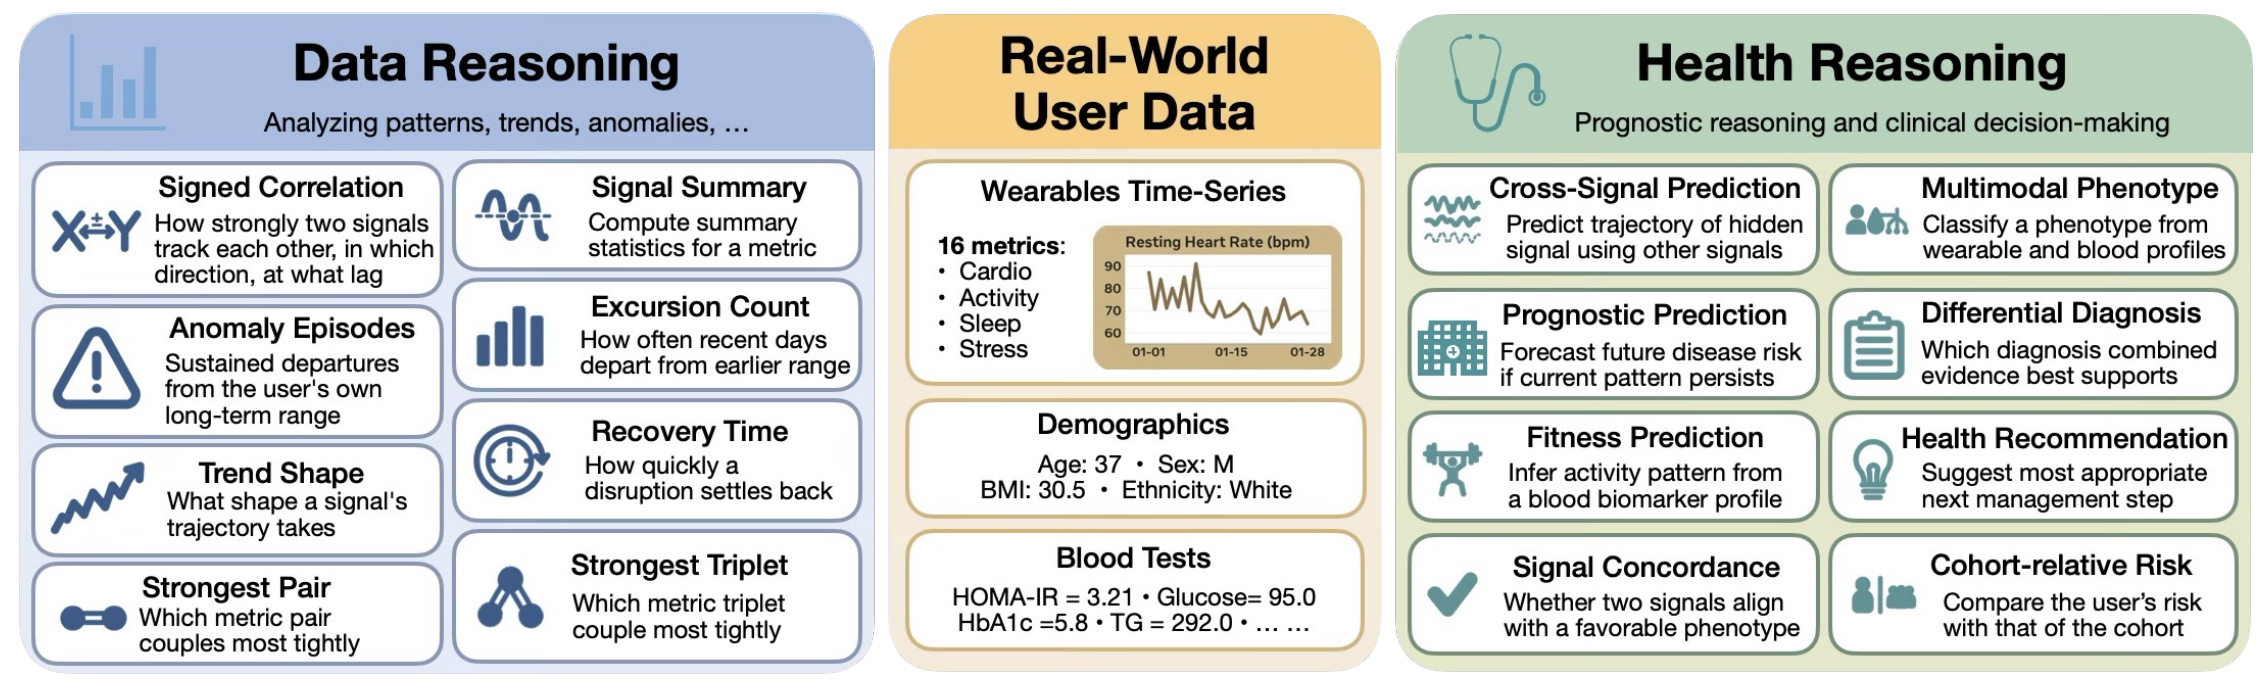
WearableQA: A Benchmark for Health Reasoning over Real-World Wearable Data
Ji Soo Lee*, Xilun Chen*, Pierce Chuang, Ashish Shenoy, Jason Wei, Dohwan Ko, Hyunwoo J. Kim, Benoit Corda
Preprint
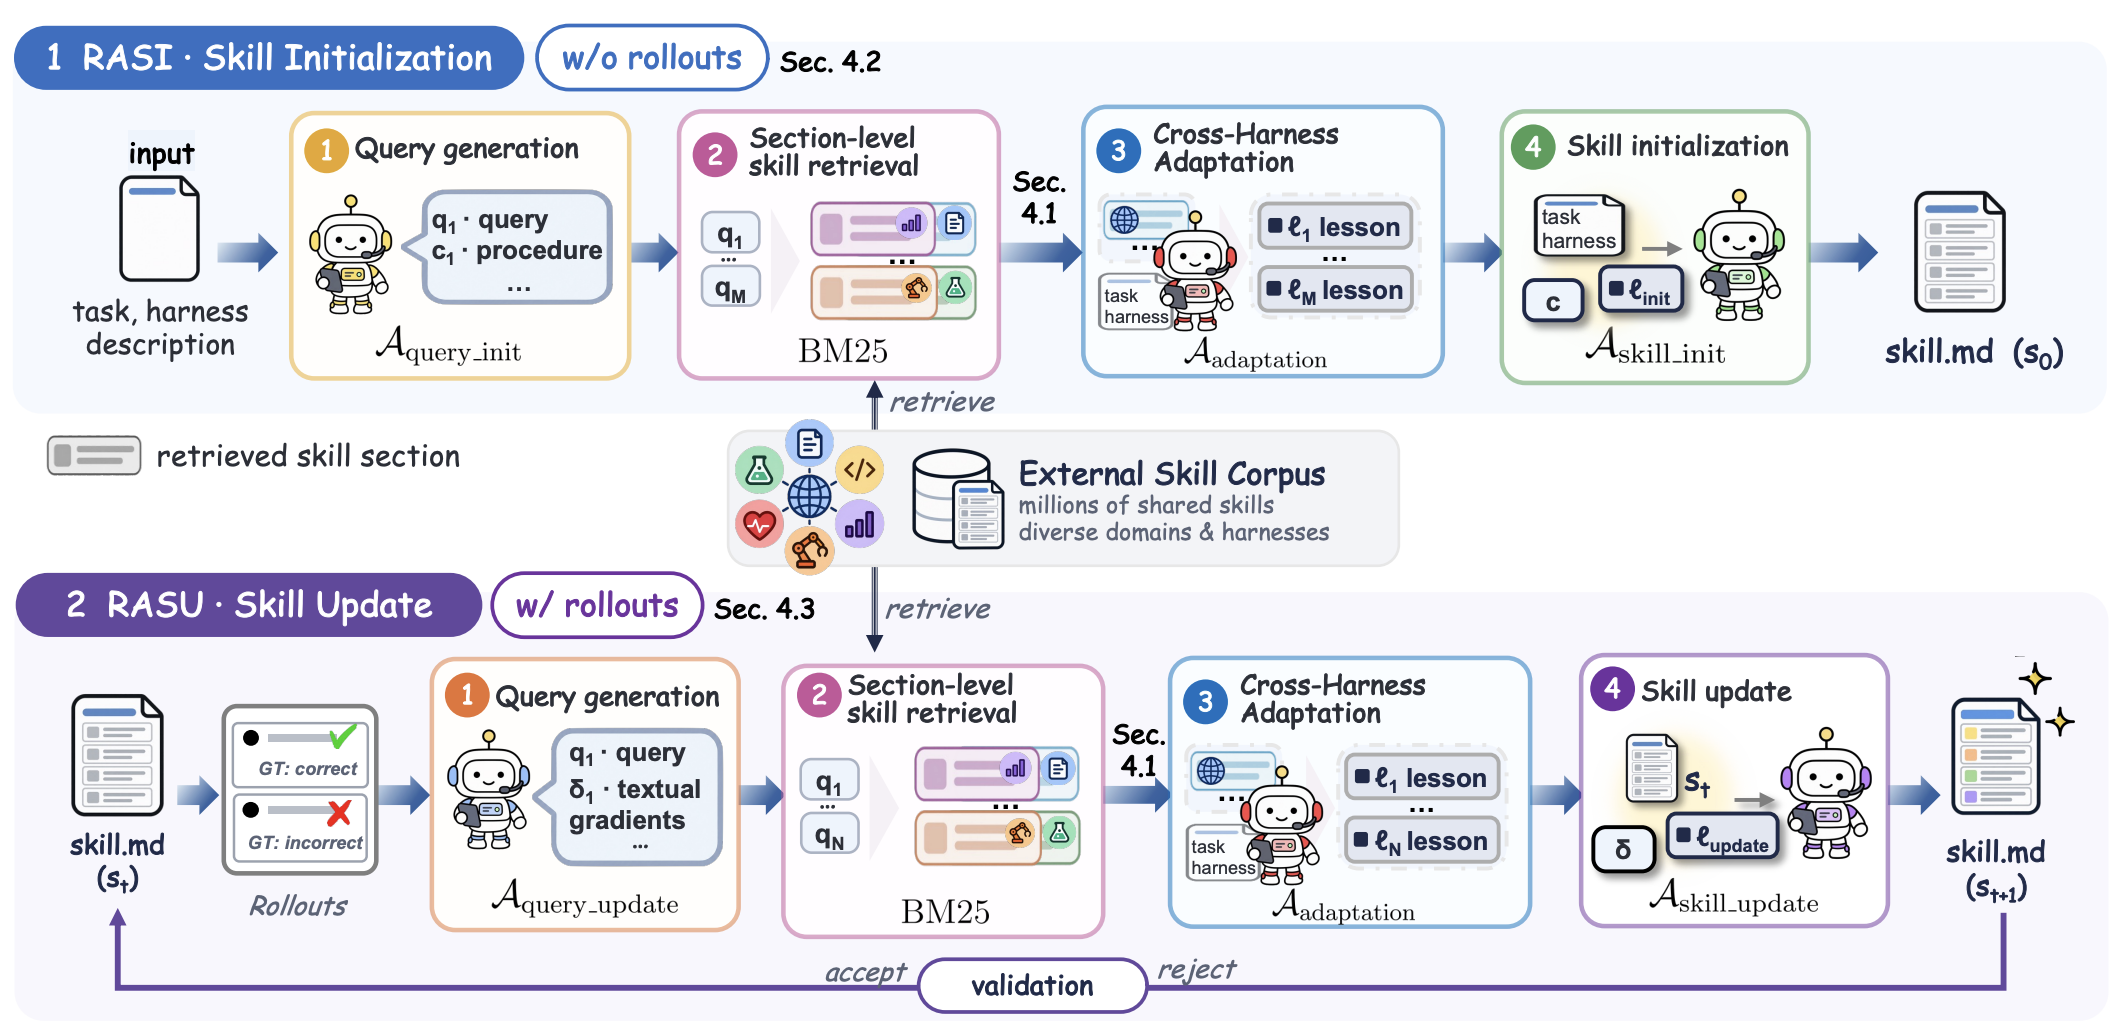
Retrieval-Augmented Skill Optimization via Cross-Harness Adaptation
Jaewon Chu, Ji Soo Lee, Jihwan Park, Dohwan Ko, Jeehye Na, Seunghun Lee, Taehoon Lee, Minseo Yoon, Minseok Joo, Yunyang Xiong, Hyunwoo J. Kim
Preprint
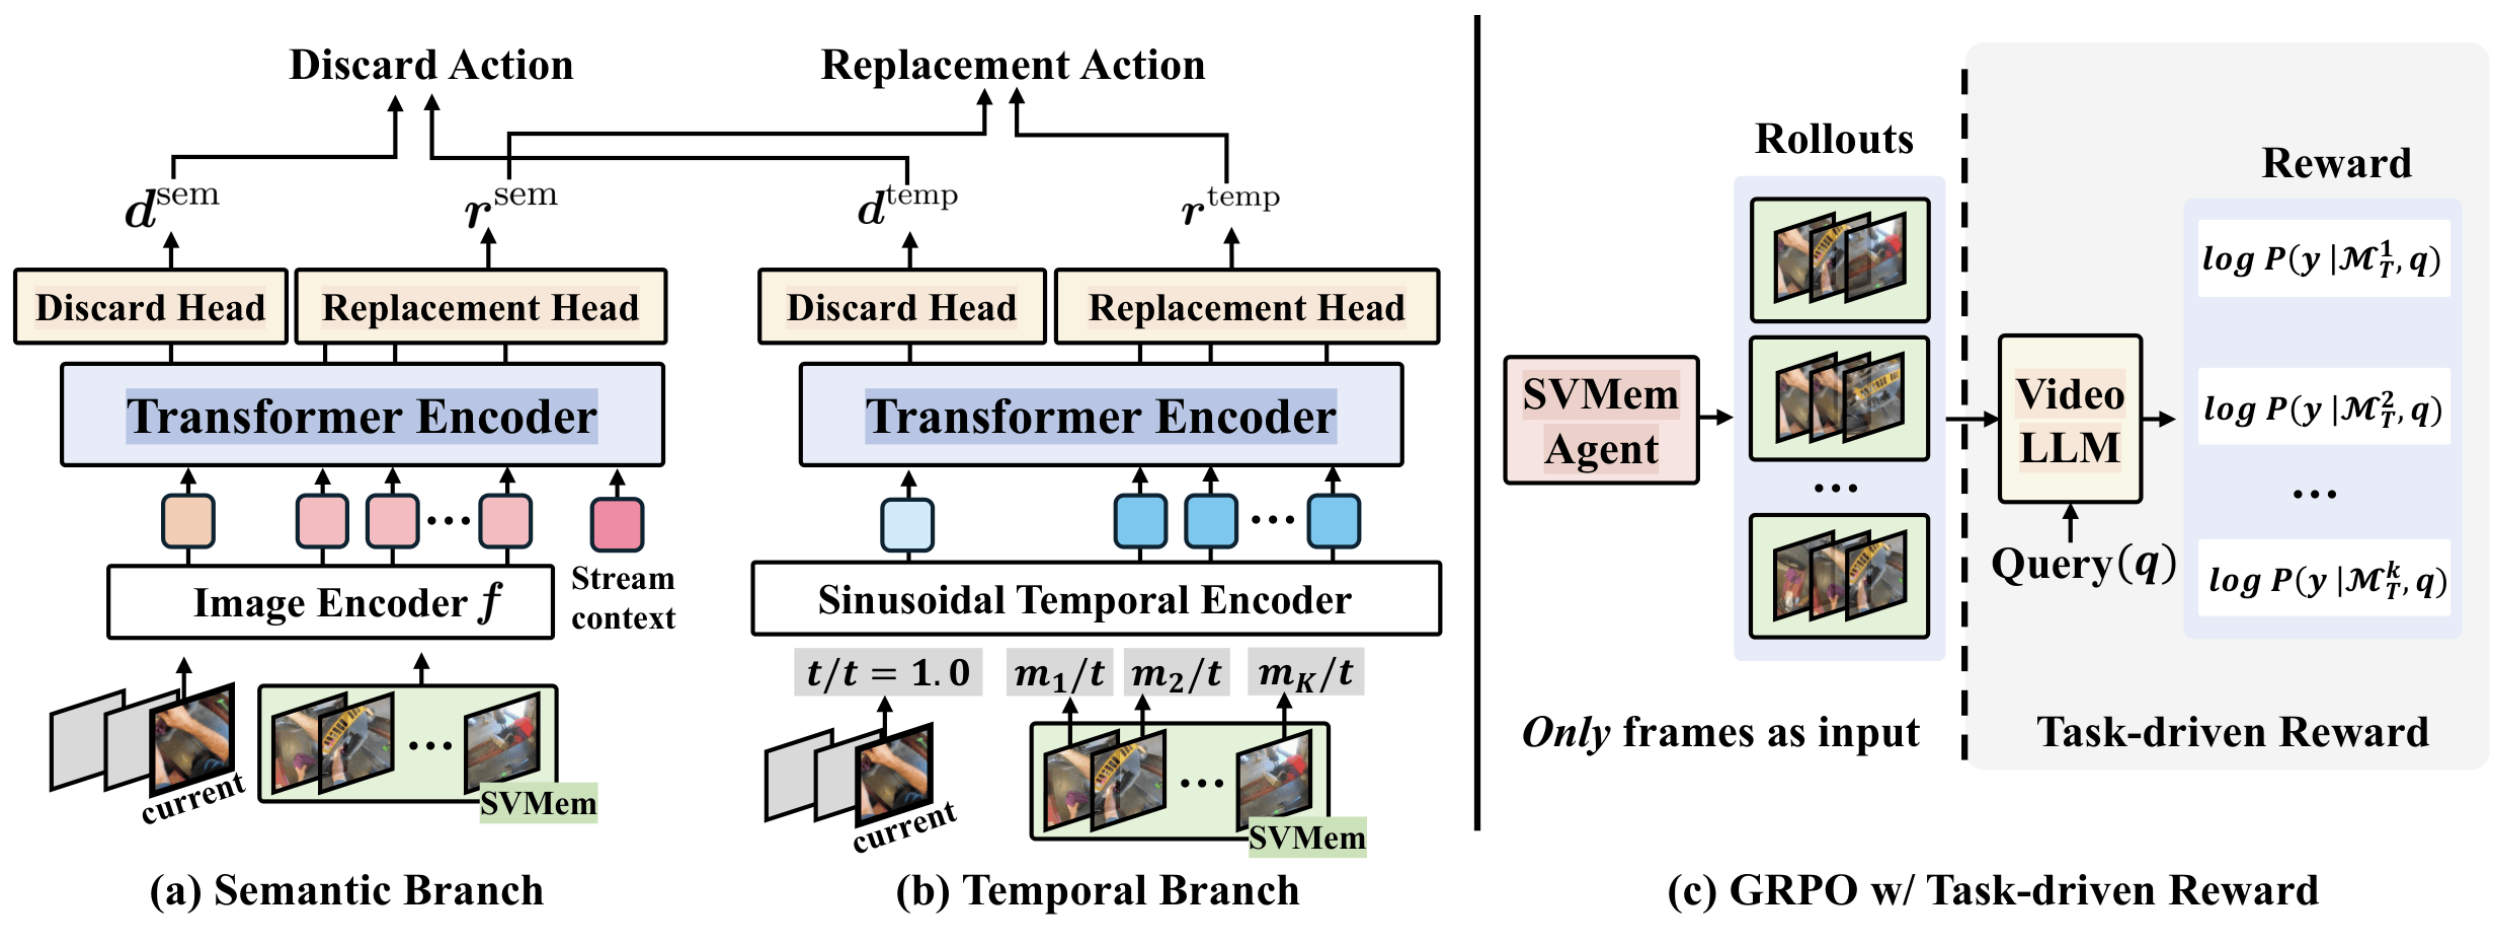
SVMemAgent: A Streaming Video Memory Agent for Query-Agnostic Online Frame Selection
Dohwan Ko, Ji Soo Lee, Pierce Chuang, Debojeet Chatterjee, Ashish Shenoy, Yichao Lu, Seungwhan Moon, Xin Luna Dong, Vikas Bhardwaj, Hyunwoo J. Kim
Wearable AI Workshop, ECCV 2026
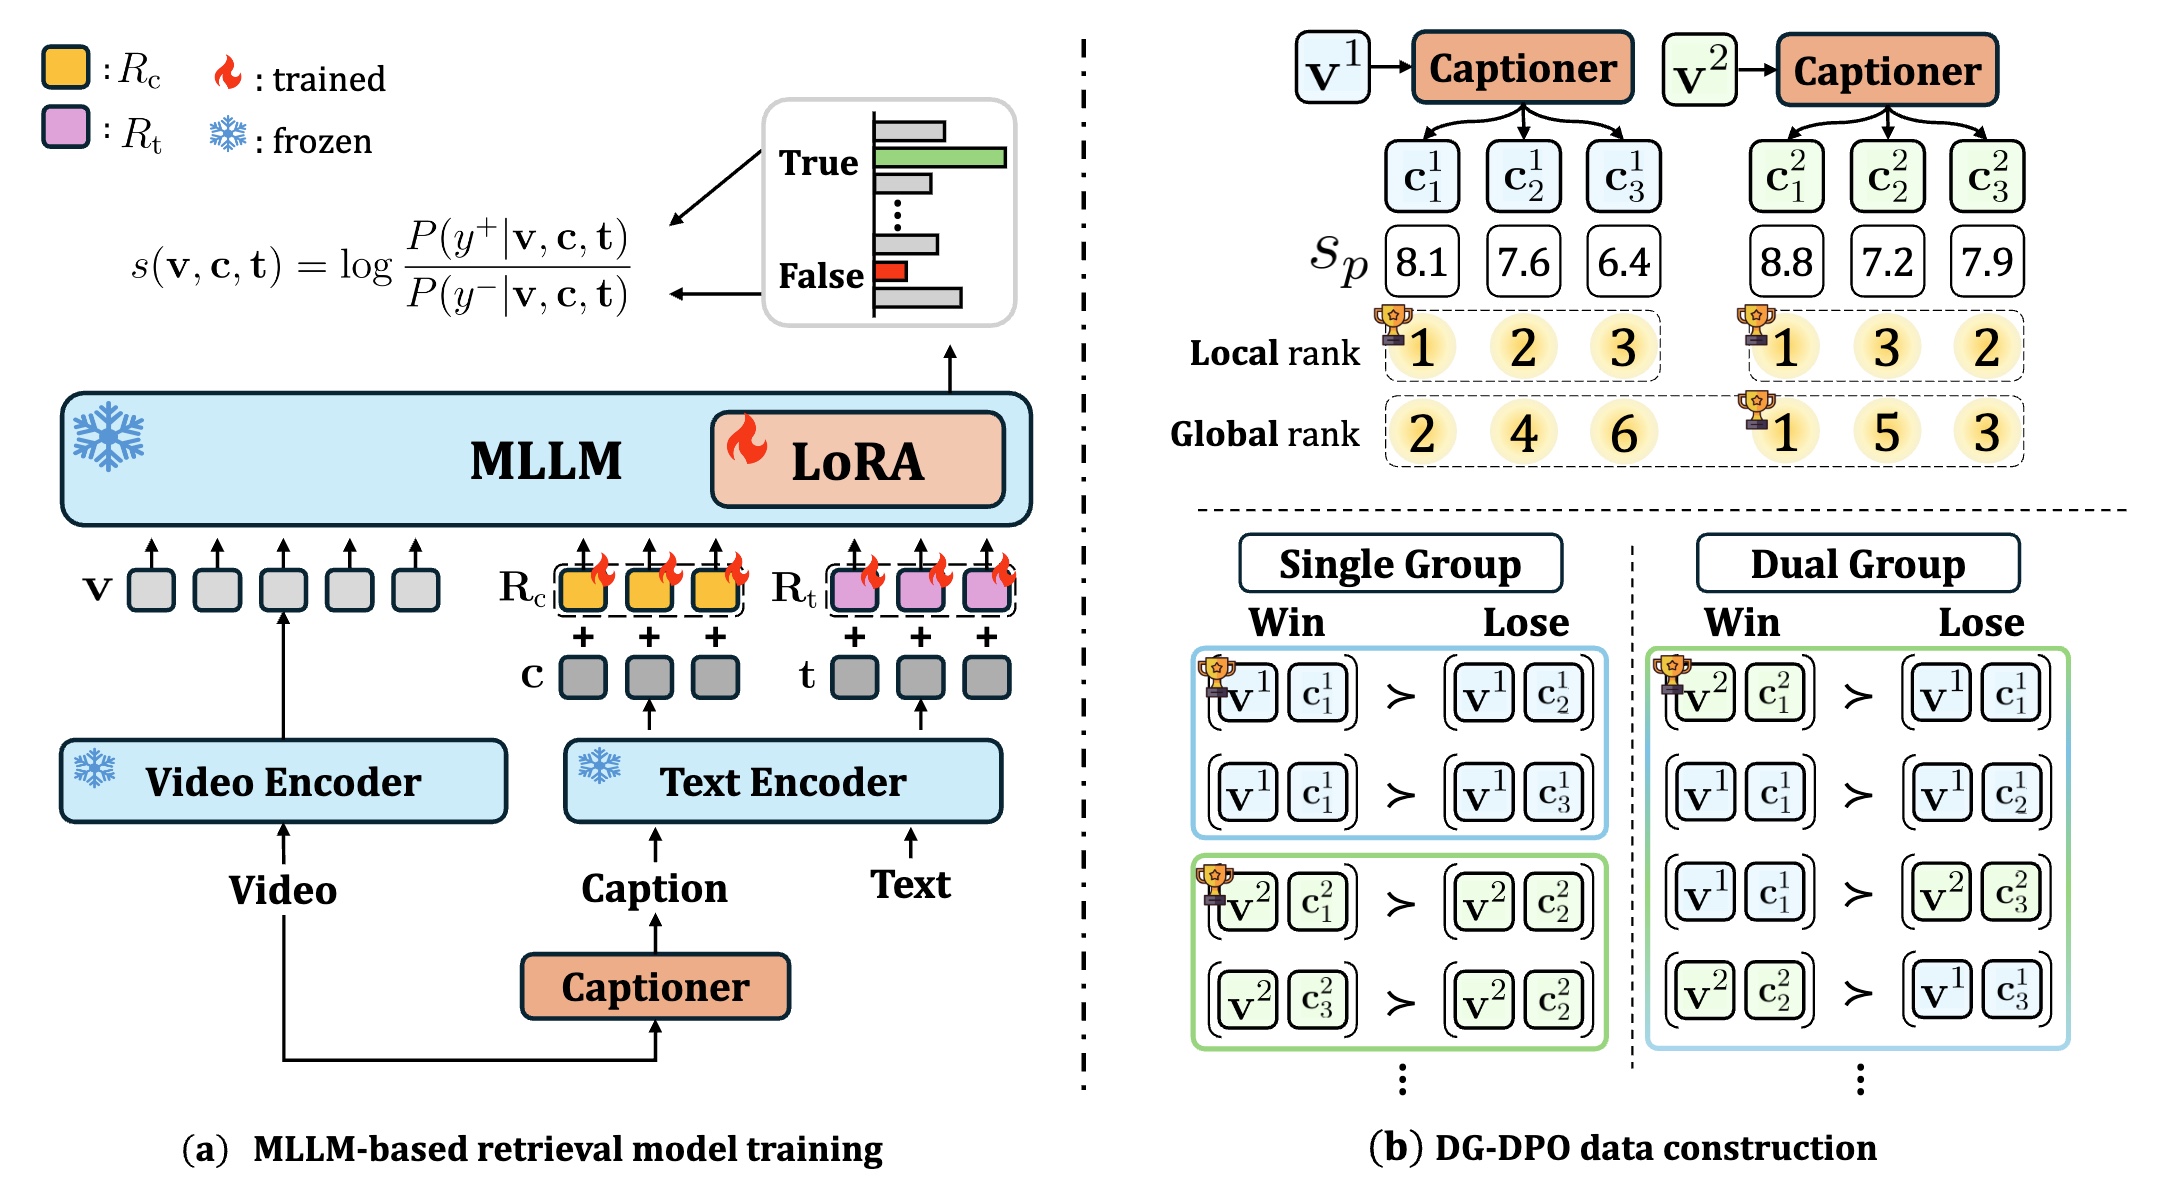
Captioning for Text-Video Retrieval via DualGroup-Direct Preference Optimization
Ji Soo Lee, Byungoh Ko, Jaewon Cho, Howoong Lee, Jaewoon Byun, Hyunwoo J. Kim
EMNLP 2025 findings
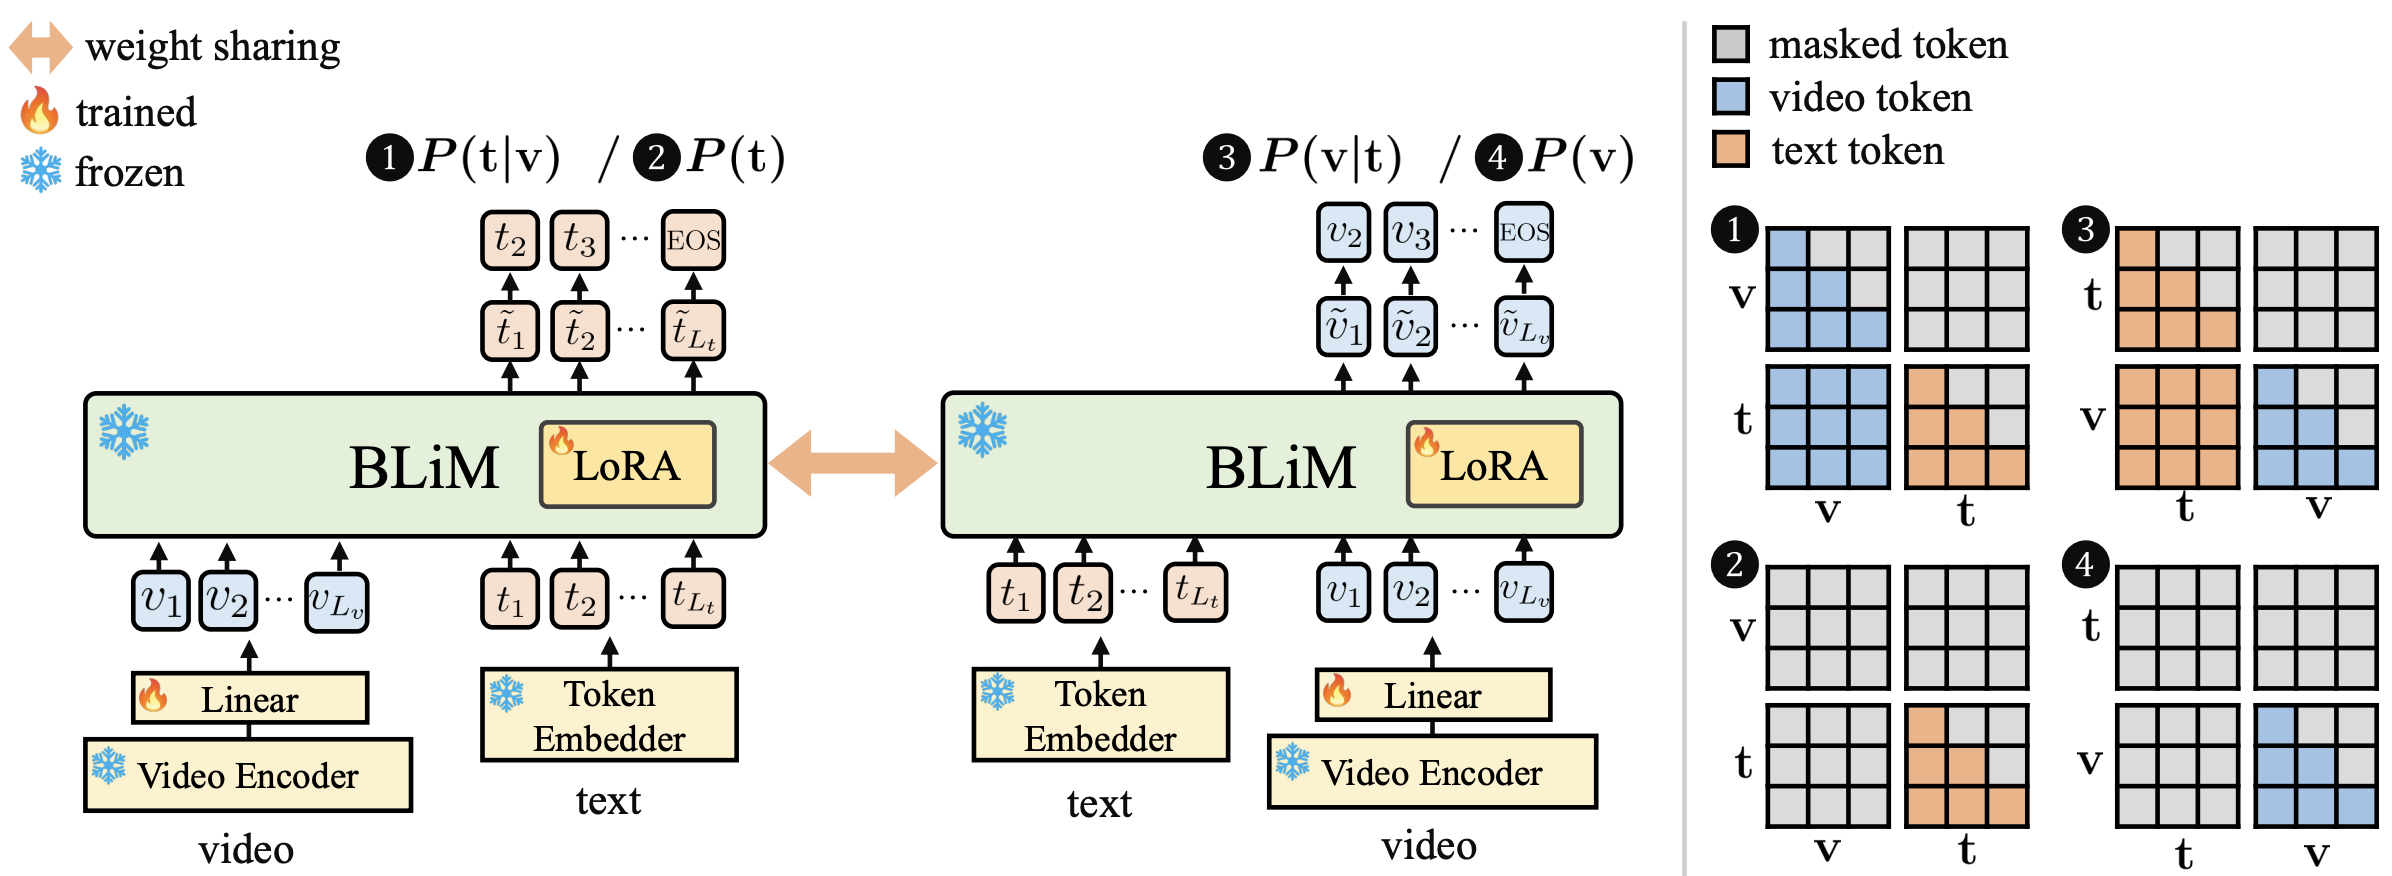
Bidirectional Likelihood Estimation with Multi-Modal Large Language Models for Text-Video Retrieval
Dohwan Ko*, Ji Soo Lee*, Minhyuk Choi, Zihang Meng, Hyunwoo J. Kim
ICCV 2025 Highlight
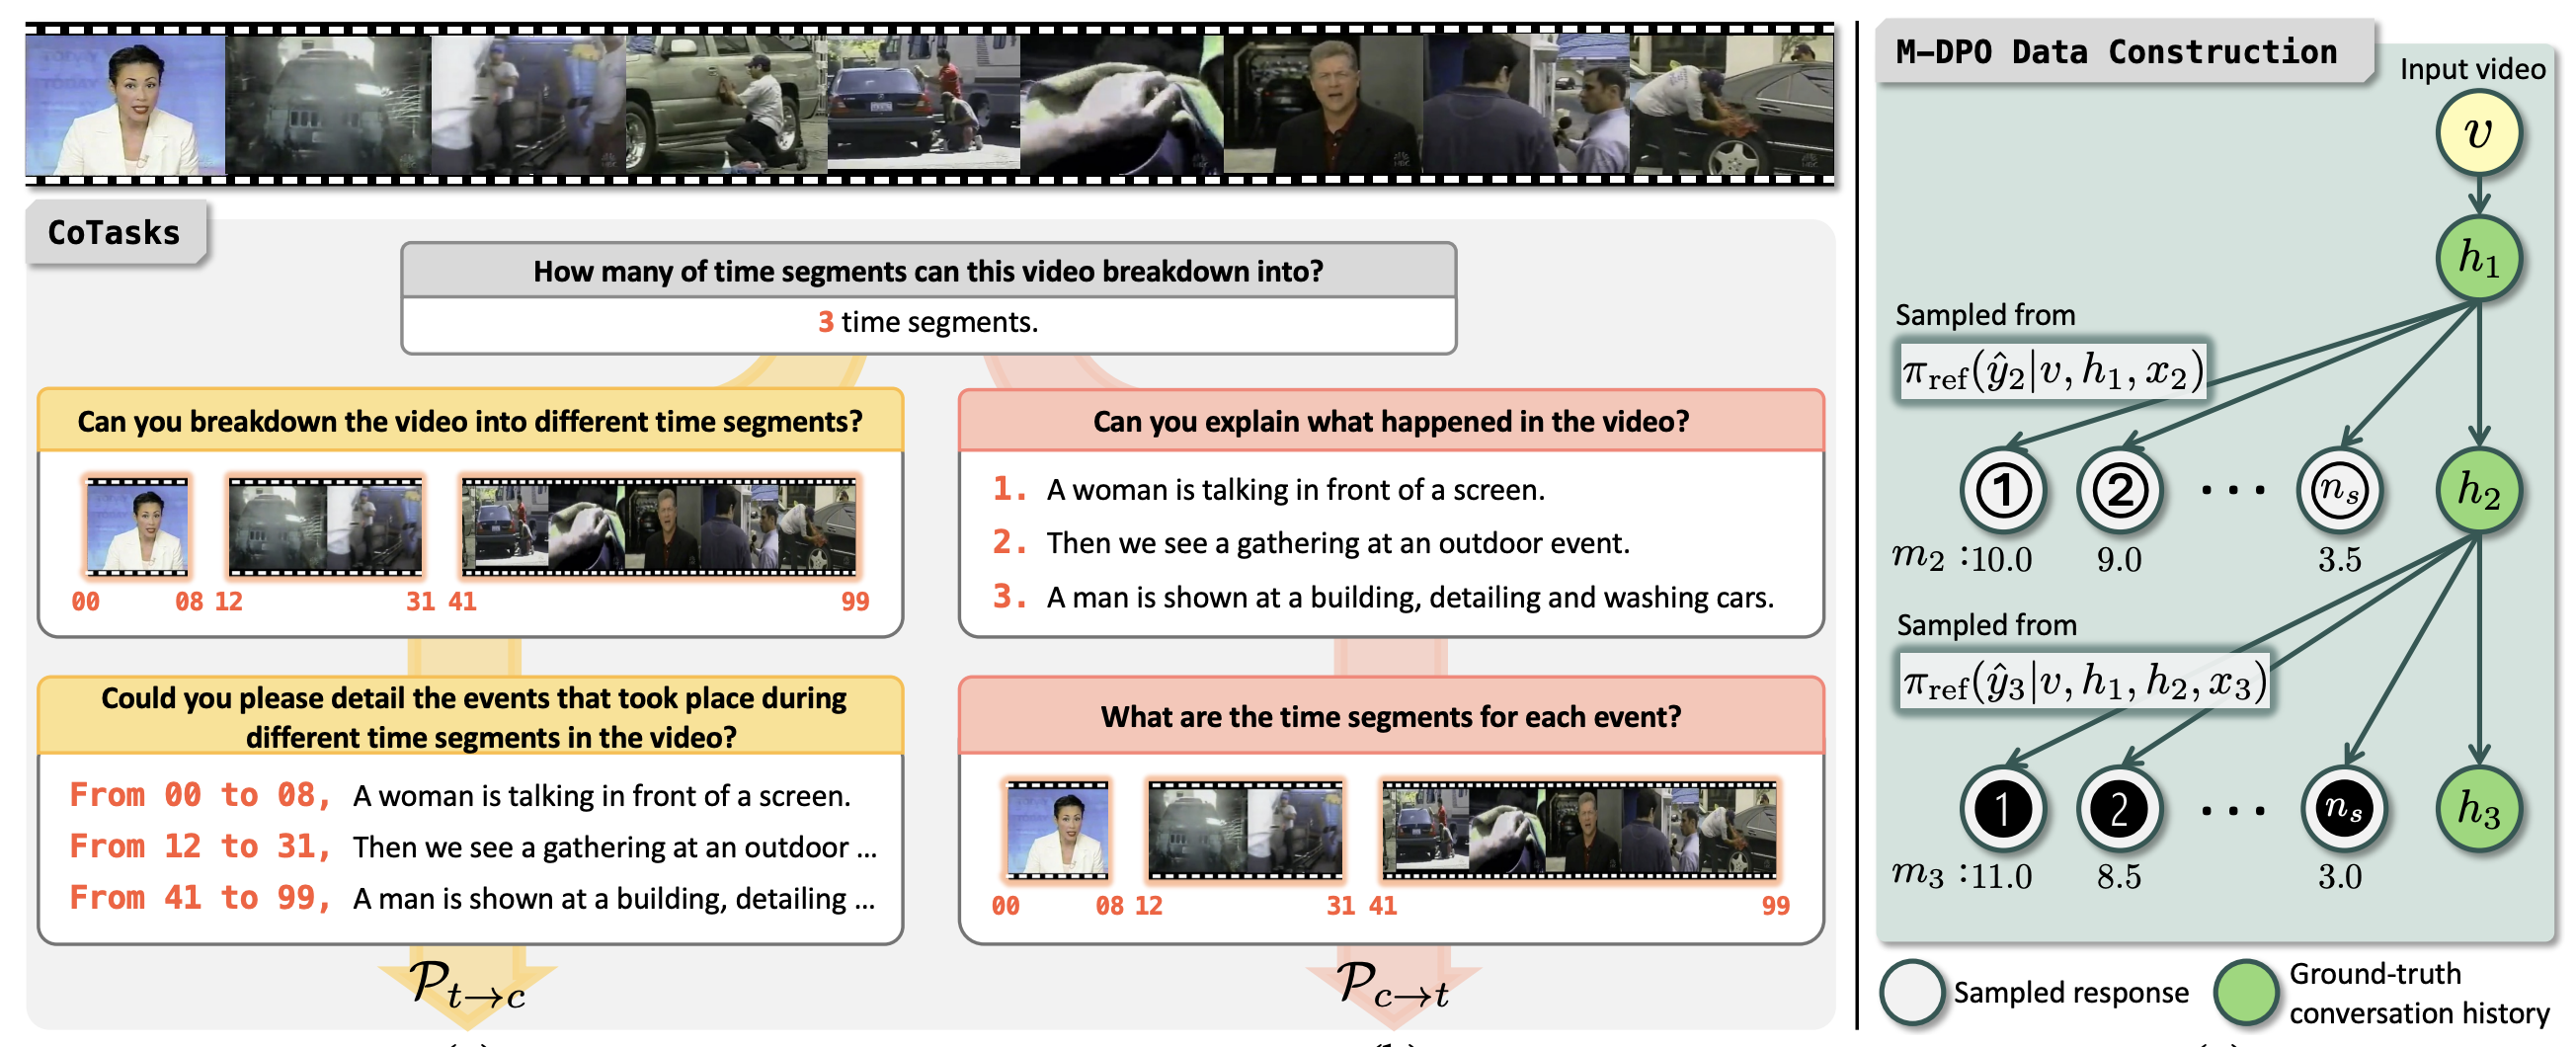
VidChain: Chain-of-Tasks with Metric-based Direct Preference Optimization for Dense Video Captioning
Ji Soo Lee*, Jongha Kim*, Jeehye Na, Jinyoung Park, Hyunwoo J. Kim
AAAI 2025
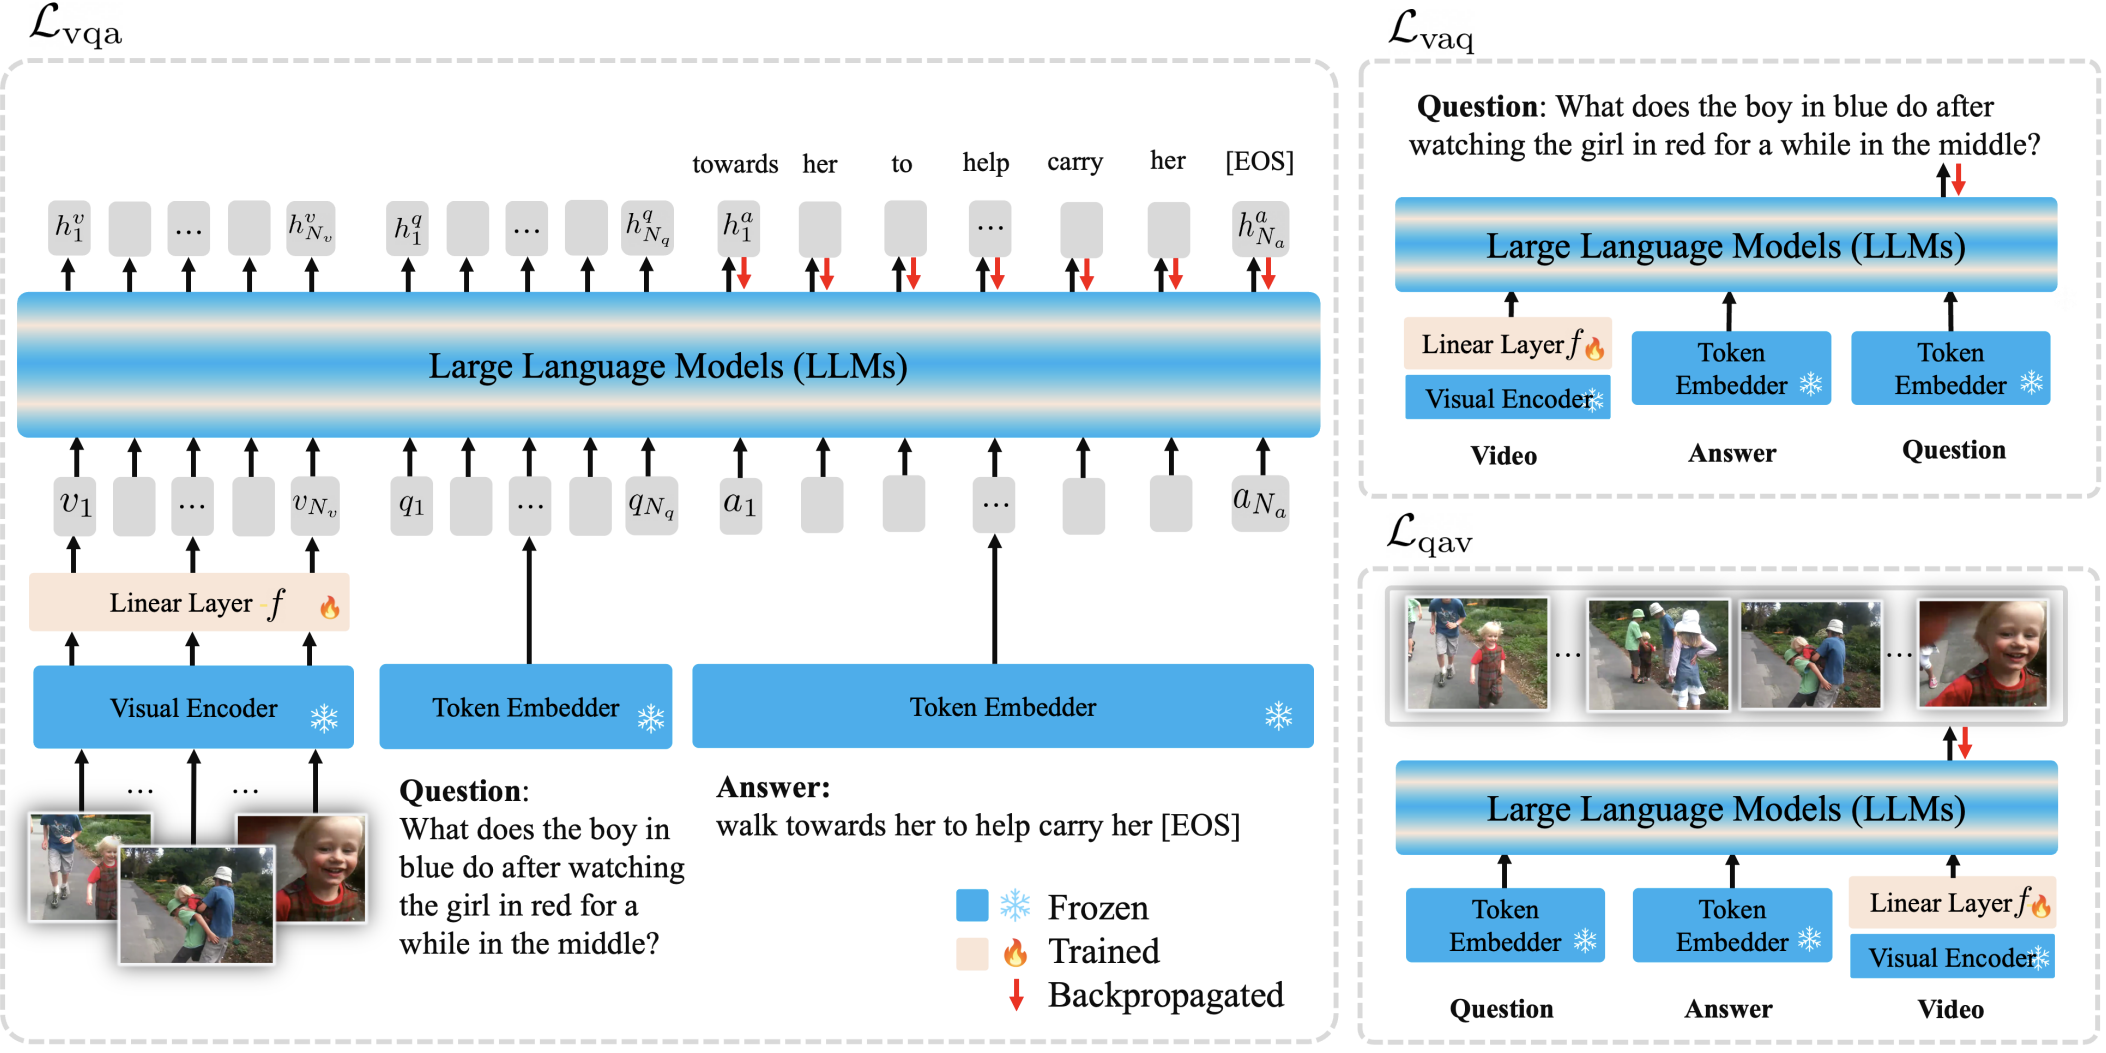
Large Language Models are Temporal and Causal Reasoners for Video Question Answering
Dohwan Ko*, Ji Soo Lee*, Wooyoung Kang, Byungseok Roh, Hyunwoo J. Kim
EMNLP 2023
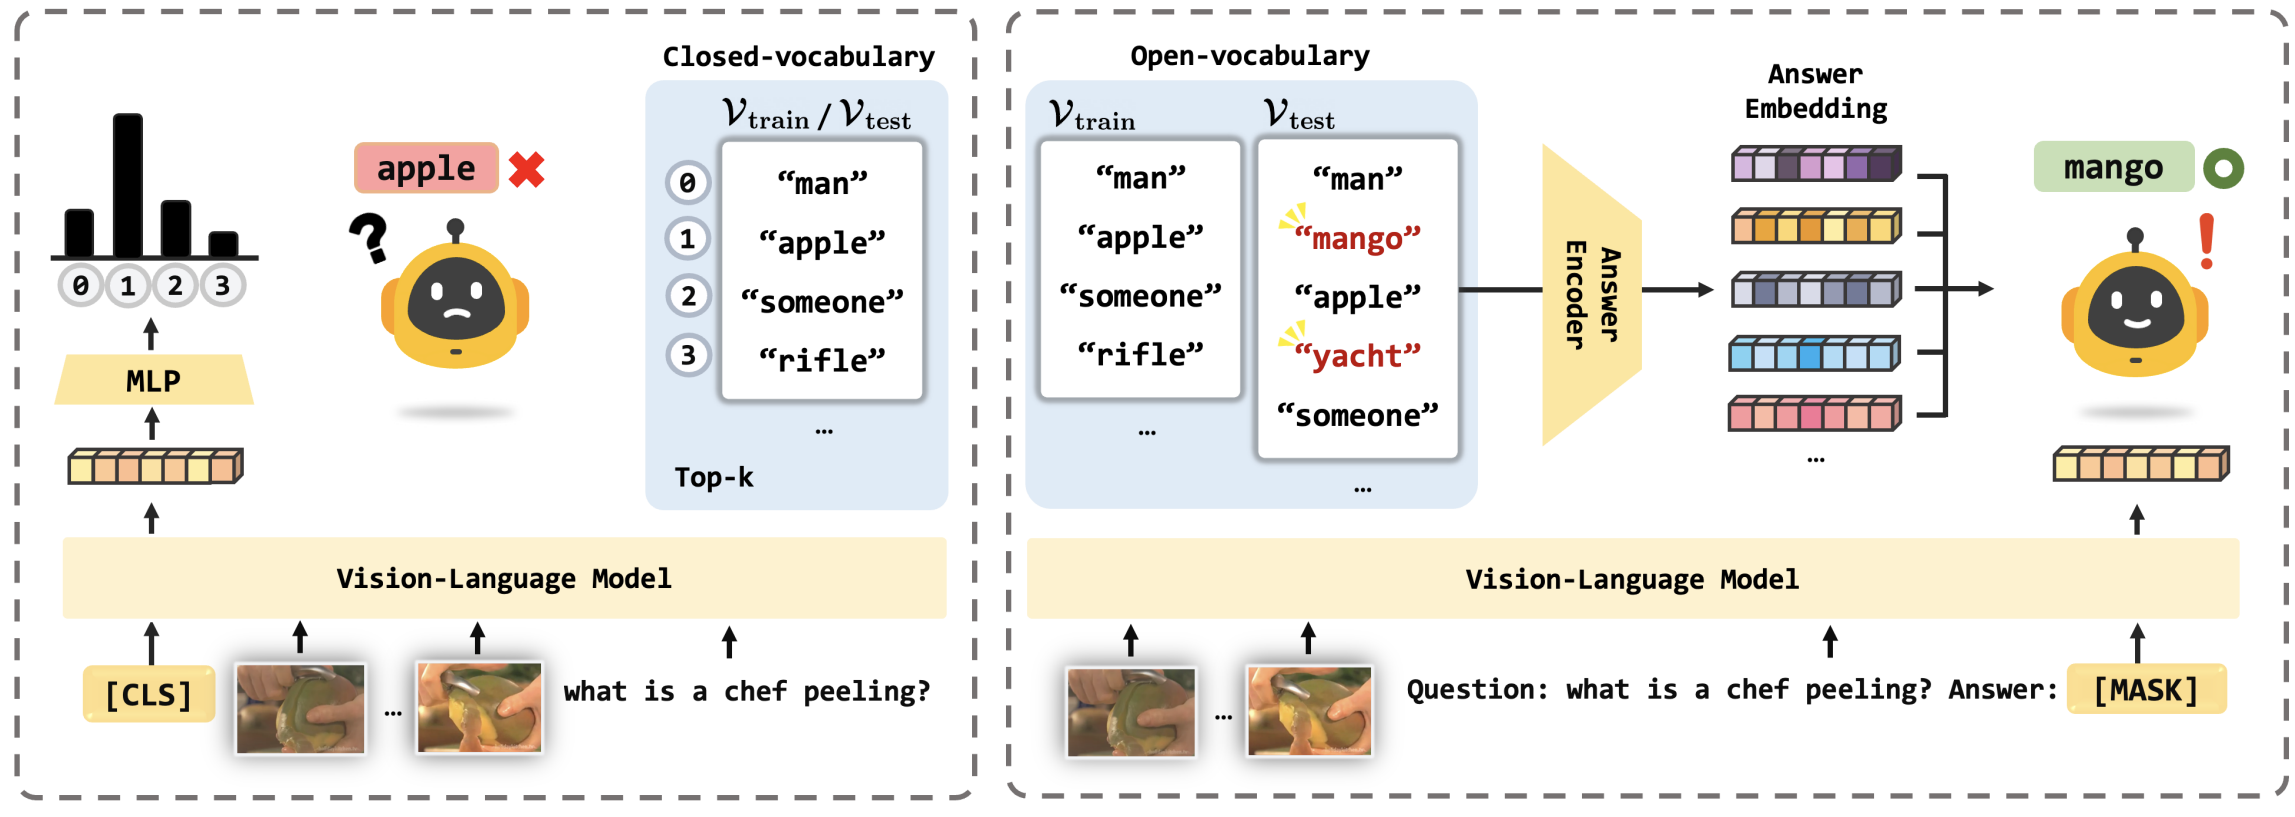
Open-vocabulary Video Question Answering: A New Benchmark for Evaluating the Generalizability of Video Question Answering Models
Dohwan Ko, Ji Soo Lee, Miso Choi, Jaewon Chu, Jihwan Park, Hyunwoo J. Kim
ICCV 2023
Vitæ
Full Resume in PDF.
-
Meta Menlo Park, CA · 2026 April - 2026 JulyResearch Intern, Reality Labs
Health Reasoning over Real-World Wearable Data
Manager: Pierce Chuang
Team: Xilun Chen, Benoit Corda, Ashish Shenoy, Jason Wei -
MLV Lab 2026 March ~Ph.D. Student (Advisor: Hyunwoo J. Kim)
Video Understanding with Foundation Models -
MLV Lab 2023 Sept - 2026 FebM.S. Student (Advisor: Hyunwoo J. Kim)
Video Understanding with Foundation Models -
Scholarship 2023 SeptAcademic Excellence Freshman Scholarship
-
Travel award 2023 AugICCV Travel Award
-
Korea University 2019 March - 2023 AugB.S. Student in Computer Science